Overview
At the bare minimum, save your manuals as files you can open. Asking an AI about them is a nice extra.
Document chat is retrieval-assisted generation: the application finds pieces of your files and gives them to a model to help answer a question. It can be useful for finding a maintenance instruction in a long manual. It can also pick the wrong passage or invent a connection that the source doesn't support.
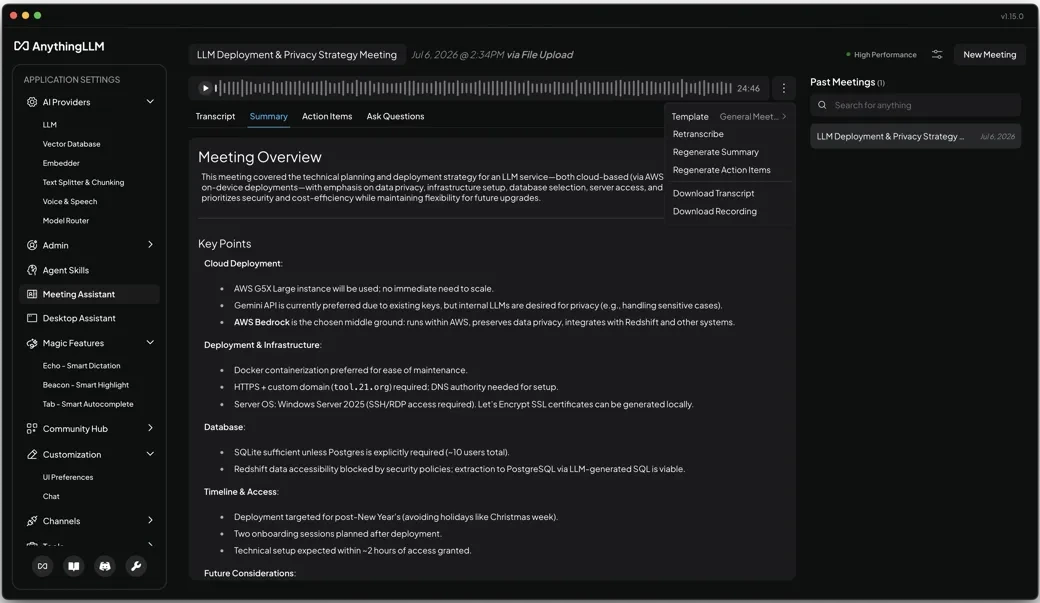
AnythingLLM's desktop edition is for one user on one device; Docker adds browser access, multiple users and workspace controls. Start with Desktop if a shared service isn't needed. Its documented basic-experience recommendation is 16 GB RAM and an 8-core CPU, with actual model inference the main hardware bottleneck.
Keep readable PDFs and text files in a normal folder outside the AI workspace as well. If indexing or inference fails during an outage, you should still be able to open the manual directly. None of this requires uploading identity documents or medical records as a first test.
What you'll need
- A computer that meets the current AnythingLLM requirements
- Official Desktop installation, or Docker if shared access is necessary
- Local inference, embedding and vector-storage providers
- A small collection of lawfully obtained, readable manuals
- Known-answer questions for checking retrieval
Tool considerations
AnythingLLM
- Good fit
- Searching and summarizing a selected folder of manuals.
- What stands out
- A document-first workflow, with a desktop option that avoids managing a shared server. Sources can help you check a generated answer.
- The trade-off
- A local-looking app can still use hosted providers or connectors. Scanned or poorly formatted files can produce weak retrieval results.
- Before going offline
- Select local inference, local embeddings and local vector storage. Download required models, finish indexing, then test with a new document offline.
Optional Desktop Pro subscription; the free local edition remains available. Pro periodically validates its license, so uninterrupted offline Pro use isn't confirmed.
Buy Desktop ProInstructions
Choose a narrow library
Begin with equipment manuals or non-sensitive household reference files. Prefer current documents with a clear publisher and date. Keep medical or legal material separate and never treat document chat as professional advice.
Check that the text is usable
Open each file and search for a phrase. A photographed or scanned PDF may need OCR. Check the OCR against the original, especially numbers and warnings; an extraction error can change an instruction before the model ever sees it.
Install the appropriate edition
Use the official Desktop download for a single computer. Choose Docker only when browser sharing or multiple users are required, and review its workspace controls. Keep the app version and setup notes with your reference folder.
Select local providers
Choose a local language-model provider and let its download finish. Inspect the embedding provider and vector storage too. A hosted inference or embedding provider means the workflow isn't fully local, even if the app is installed on your laptop.
Create and populate a workspace
Create one workspace for a coherent topic, add the selected files and complete the app's indexing/embedding step. Wait for processing to finish; merely placing a PDF in a folder isn't the same as indexing it.
Ask an answerable question
Ask for a specific instruction stated in the manual, request the supporting passage and tell the model to say when the answer is absent. Open the cited original and compare. A citation helps inspection but doesn't guarantee correctness.
Try an absent answer
Ask about something not covered by the library. If the model confidently invents a procedure, don't trust its confidence on other questions. Refine the workflow and use it for locating text rather than making unsupported decisions.
Test fresh indexing offline
Disconnect internet, reopen the application, add a different small document and ask a known-answer question. This checks the embedding path as well as chat. Disable optional agents and connectors that rely on online services.
Retain a recoverable collection
Back up original files, source notes and the workspace using the installed version's procedures. Use appropriate encryption for sensitive content and test recovery. Local application data and exported chats aren't automatically encrypted backups.
Check it works offline
- Original files are readable and searchable without the AI application.
- Inference, embeddings and storage are configured locally.
- A new document can be processed with internet disabled.
- Known-answer replies agree with the original source passages.
Things to watch for
A source-grounded answer can still be wrong. Verify anything involving safety, treatment or legal obligations in the original.
Don't use agents or remote connectors as part of an offline dependency chain.
Only import content you are entitled to store, and preserve licenses if sharing a library.
Sources and further reading
Related how-tos
Save and protect important offline documents
Build a readable reference folder, separate private records, and verify an encrypted backup you can unlock without the internet.
Read the how-toRun an offline AI assistant on your laptop
Start with LM Studio, download a model that fits your computer and prove both chat and document questions work disconnected.
Read the how-toRun an offline knowledge and maps drill
Restart devices, cut internet access and test fresh work — not just a cached page or an old chat — before depending on the kit.
Read the how-to